MANAGED INFERENCE
Managed inference, built your way.
Give every customer and every internal team a private inference endpoint in minutes. Compose the service from the engines and tools you choose, and run it on your own infrastructure.
Give every customer and every internal team a private inference endpoint in minutes. Compose the service from the engines and tools you choose, and run it on your own infrastructure.
Months of work and a dedicated platform team.
One opinionated path that can’t bend to your hardware, models or users.
Teams and customers wait while GPUs sit underused.
Serve your own teams, or build an offering for your customers.
Private inference for every internal team: Every team gets its own endpoint. No ticket queue, no sharing.
The foundation for your own inference offering: Offer managed inference under your brand, not just GPU-hours.
One definition creates the cluster, installs the inference service in the right order, and hands over an endpoint.
vMetal provisions GPU nodes as bare metal or VMs through one stable API.
Each customer or team gets an isolated cluster on Private Nodes: dedicated GPUs, no sharing.
The Stack installs the engine, gateway, autoscaling and observability, health-gated step by step.
Your user gets an endpoint, API keys and a usage view.
A single, rigid offering doesn’t fit the reality on the ground. Here’s an example inference Stack, step by step. Start with the defaults, or swap any layer for the tool you already trust.
Every step is open and forkable in the vClusterStacks repository, alongside partner Stacks like Saturn Cloud’s AI token factory.
Customers and teams see the service, nothing beneath it.
Its own isolated cluster. Nothing else visible.
Point existing code at it. No new libraries.
Create, revoke and block their own keys.
See tokens and latency. Test models first.
Each new customer or team is a deployment, not a project.
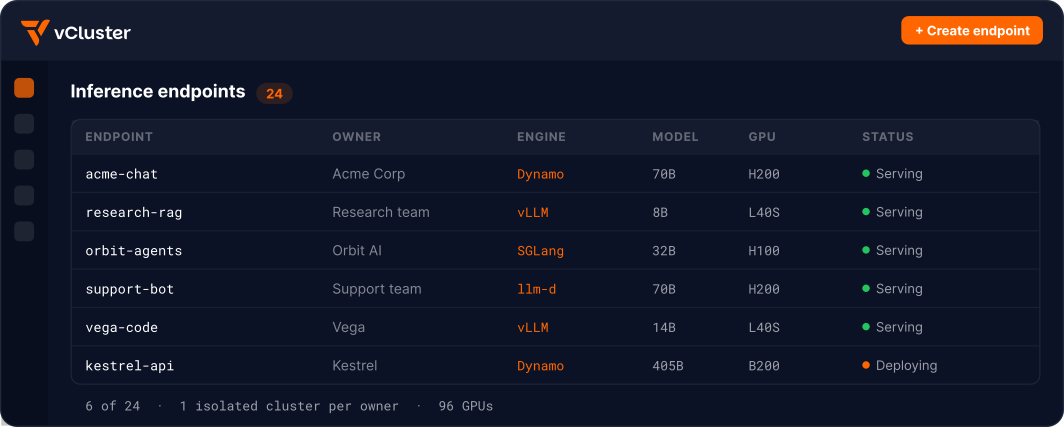
Every customer and team in one view.
Its own cluster and nodes for every owner.
Tokens and cost per owner, from the gateway.
Use our console or put your own in front.
“Adding a service to an AI cloud shouldn’t mean starting a new integration project each time. vCluster built the Saturn Cloud Stack, so an operator can deploy it like any other service. Each customer gets private inference in an environment of their own, ready to use right away, and a small team can keep adding services without adding headcount.”
Same control plane virtualization, same isolation model, same Platform console you use for every other cluster you run.
Conformant clusters with their own control plane per tenant.
Tenants see only their own partition and jobs.
Tenants see only their own projects and jobs.
Tenants see only their own head node and workers.
Get a live walkthrough built around your GPUs, your engines and your users.
