Built for GPU Cluster Node Resilience
GPU cluster node auto repair requires coordinated health signals, Machine lifecycle actions, tenant boundaries, and infrastructure repair tooling.
Replacement Capacity
GPU Node Repair Workflow
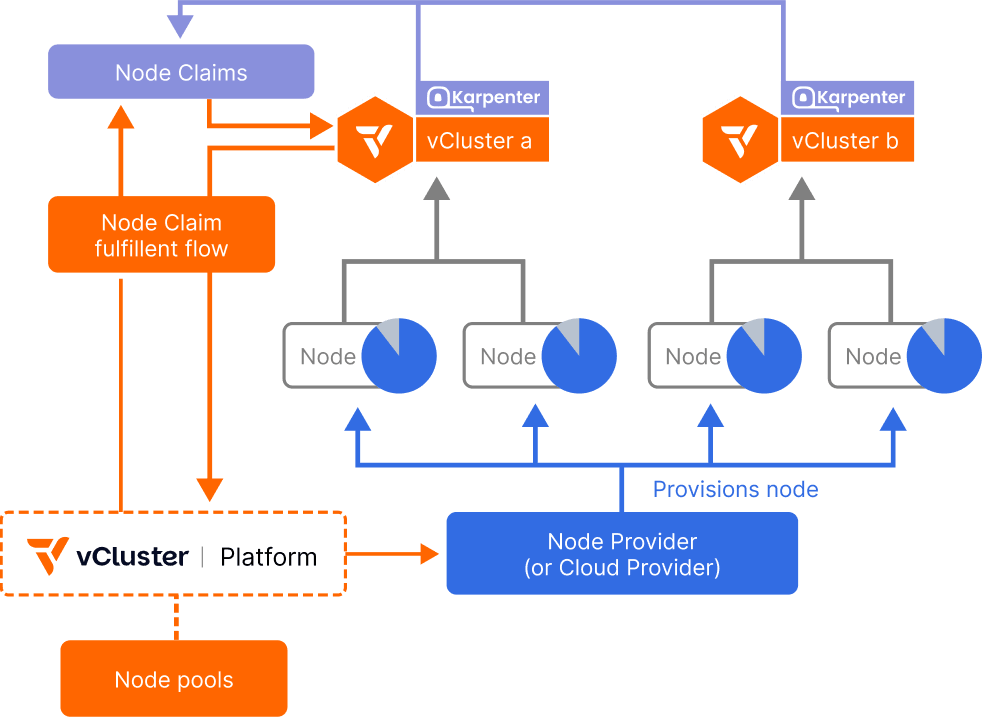
Detection, workload handling and hardware repair stay with the systems that own them. Auto Nodes then requests replacement Private Node capacity through the vMetal Machine API.
Machine Lifecycle
Full Machine Lifecycle Management
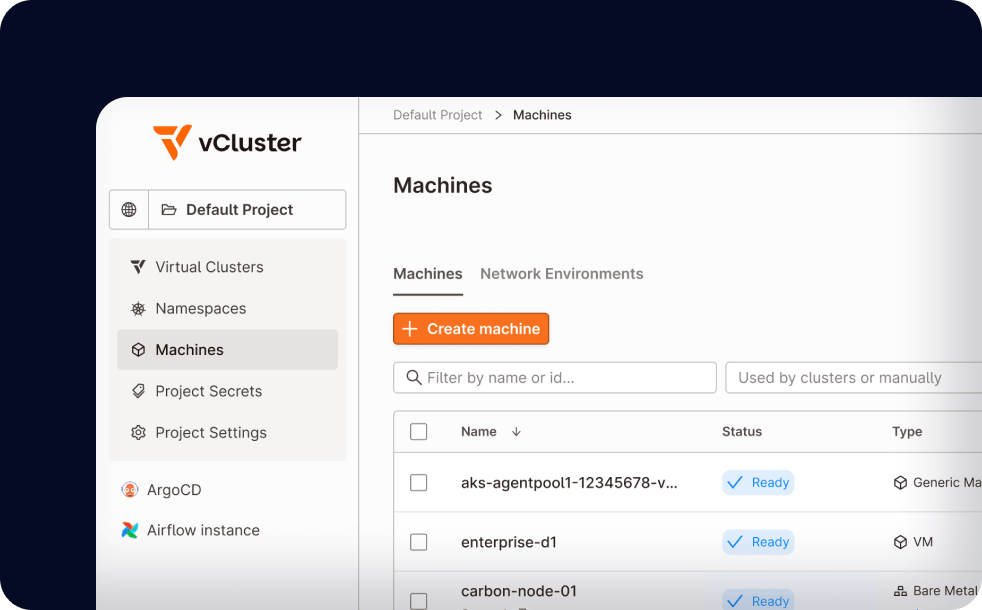
vMetal tracks Machine requests through provisioning, cluster attachment, deletion, cleaning, and return to available inventory.
Operational Reliability
Tenant Cluster Observability
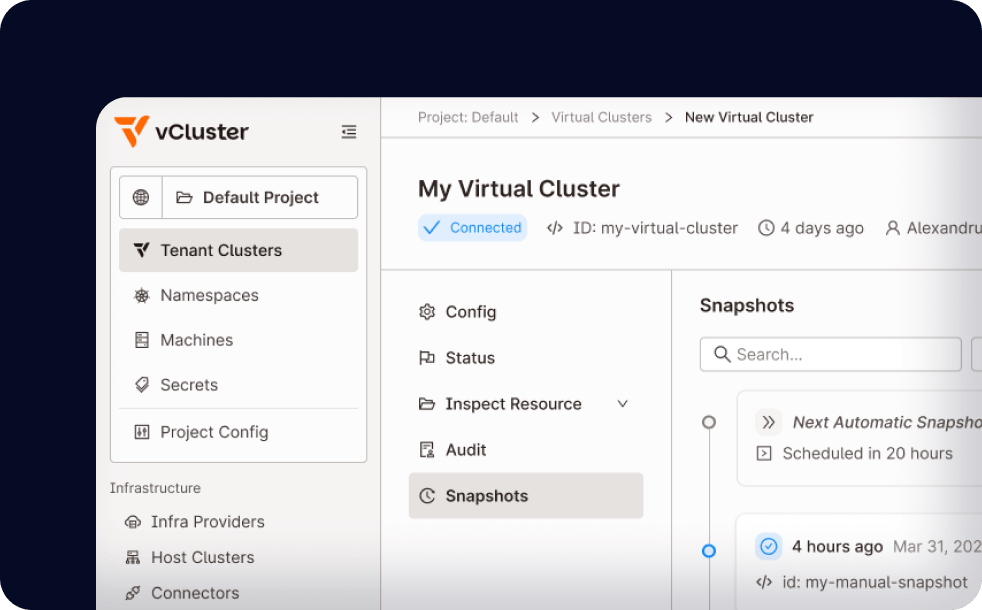
vCluster Platform provides centralized observability and operations across the tenant cluster fleet.
Built-in observability across fleet
Backup and recovery workflows
Policy and configuration management
Tenant Isolation
Tenant-Scoped Recovery
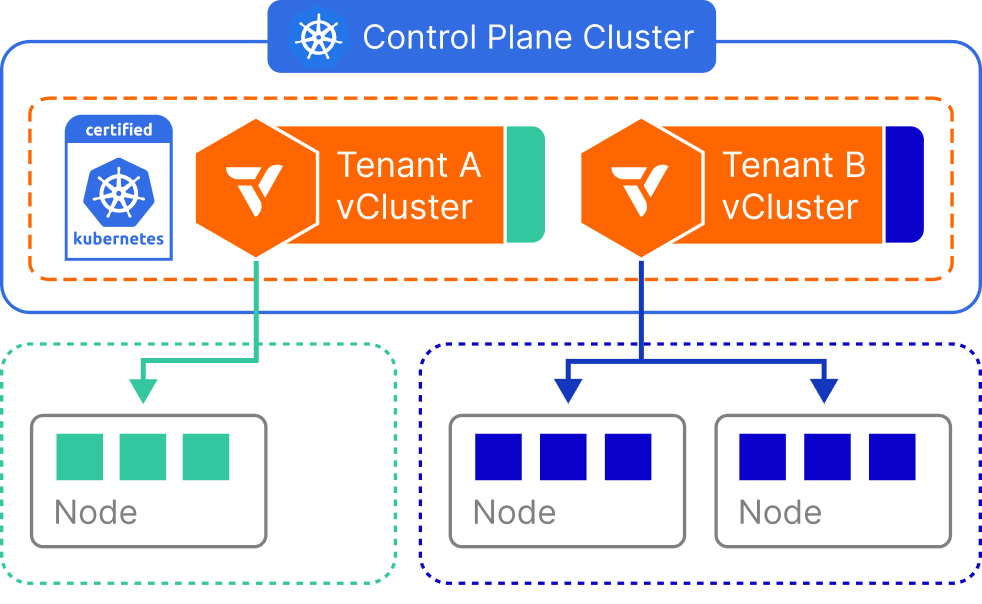
Private Nodes assign dedicated worker capacity to one production tenant cluster at a time, keeping ownership clear during recovery.
Dedicated worker nodes per tenant
Per-tenant CNI and storage
Failures scoped to one tenant
Central Control
Fleet-Wide Cluster Operations
Use one UI, CLI, and API for tenant cluster operations while infrastructure tooling handles server-specific diagnosis and repair.