ai-cloud
GPU Orchestration Platform for AI Cloud Providers
Build a GPU service beyond job scheduling. vMetal orchestrates infrastructure, and vCluster provisions separate tenant environments with dedicated Private Nodes for production workloads.
Build a GPU service beyond job scheduling. vMetal orchestrates infrastructure, and vCluster provisions separate tenant environments with dedicated Private Nodes for production workloads.
The real bottleneck is not hardware. It is the infrastructure layer above it.
Selling bare metal GPUs alone is a race to the bottom. Customers want the cloud experience your hyperscaler competitors already offer.
Building a GPU cloud platform in-house takes significant engineering time before the first tenant runs anything.
Standard Kubernetes forces you to choose. Namespace isolation is too weak. Separate physical clusters are too expensive and too slow.
vMetal supplies the machine layer. vCluster creates independent Kubernetes tenant environments with dedicated Private Nodes, while workload schedulers and AI frameworks run within the configured tenant environment. vCluster Labs serves 50+ GPU clouds & Fortune 500s.
Every layer of the stack is built for AI cloud providers running GPU workloads across many tenant environments.
Each tenant has an independent Kubernetes API, data store and RBAC boundary. Lightweight control-plane hosting reduces dedicated server requirements for GPU service orchestration; Private Nodes keep production workers tenant-specific.
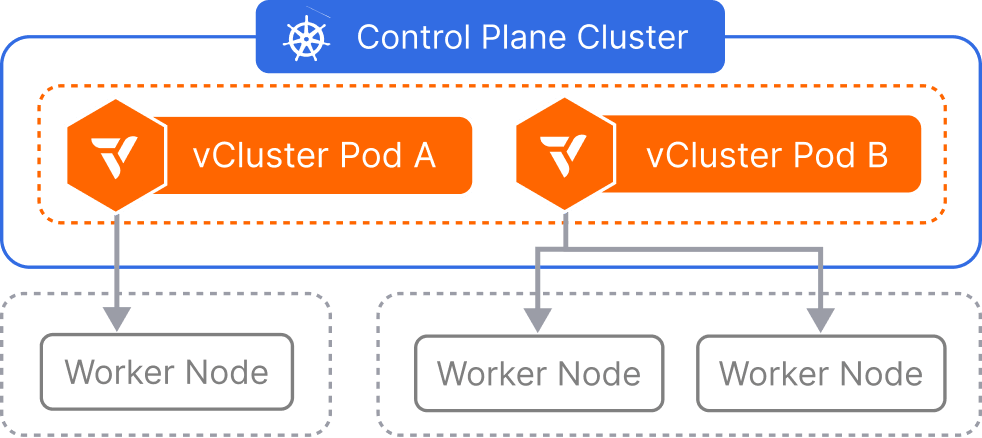
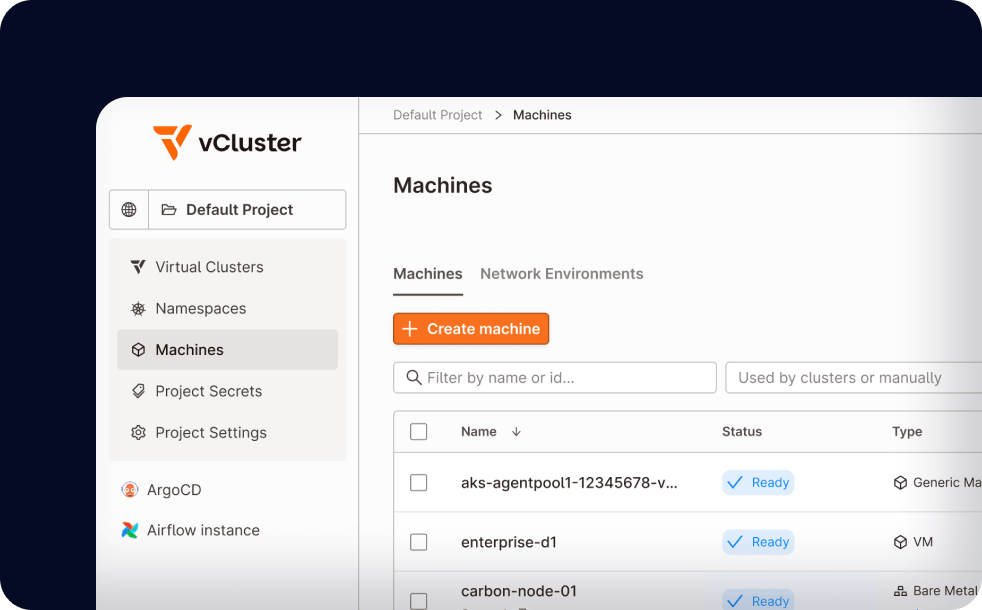
vMetal exposes one Machine API above bare metal and VM provisioning drivers. Registered inventory, images and credentials enable repeatable machine lifecycle workflows for GPU service orchestration. Network automation uses supported integrations such as Netris.
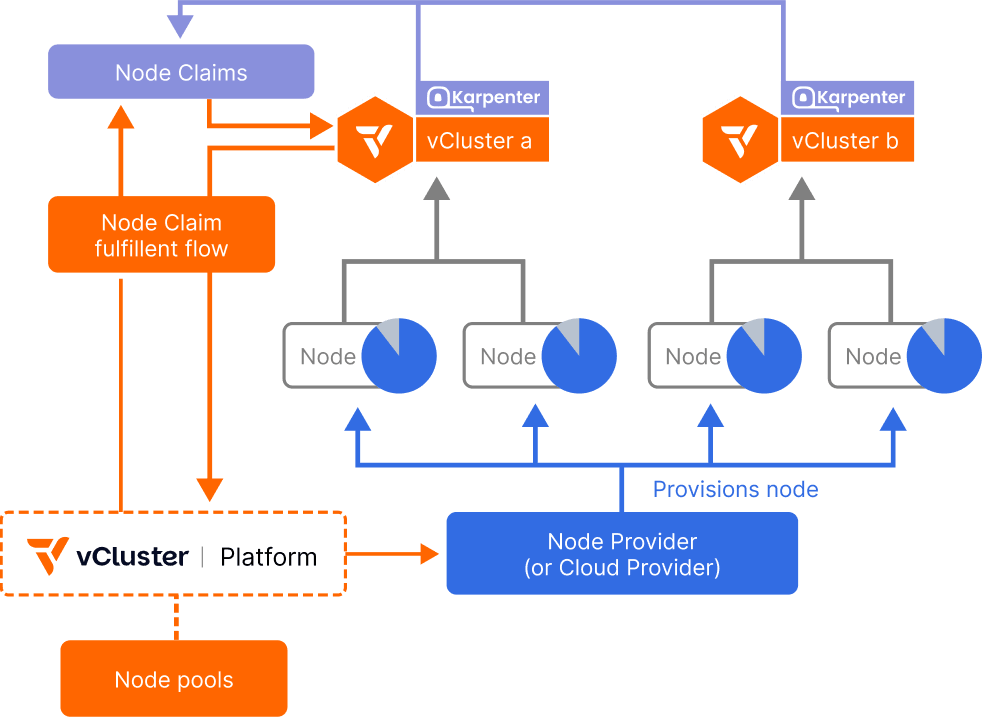
Karpenter-based Auto Nodes requests worker capacity according to configured policies. With the vMetal provider, Machine requests provision available infrastructure for GPU service orchestration; inventory, driver readiness and release rules determine actual capacity.
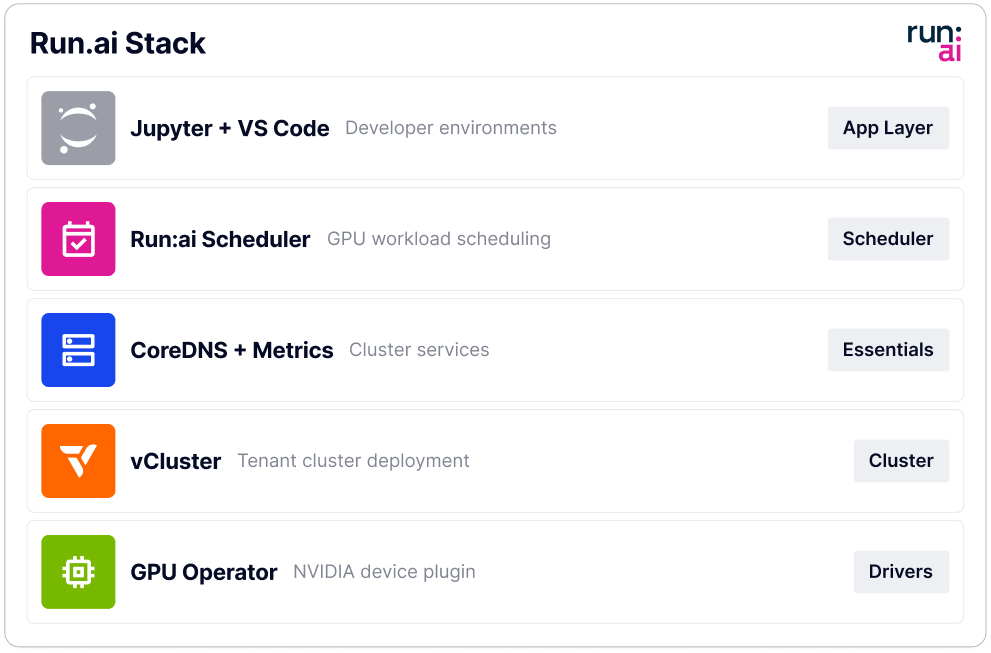
Use supported workload templates for GPU service orchestration, including the NVIDIA Run:AI partner integration. Configure GPU, network and storage prerequisites, and validate the selected template for Private Nodes before offering it to production customers.
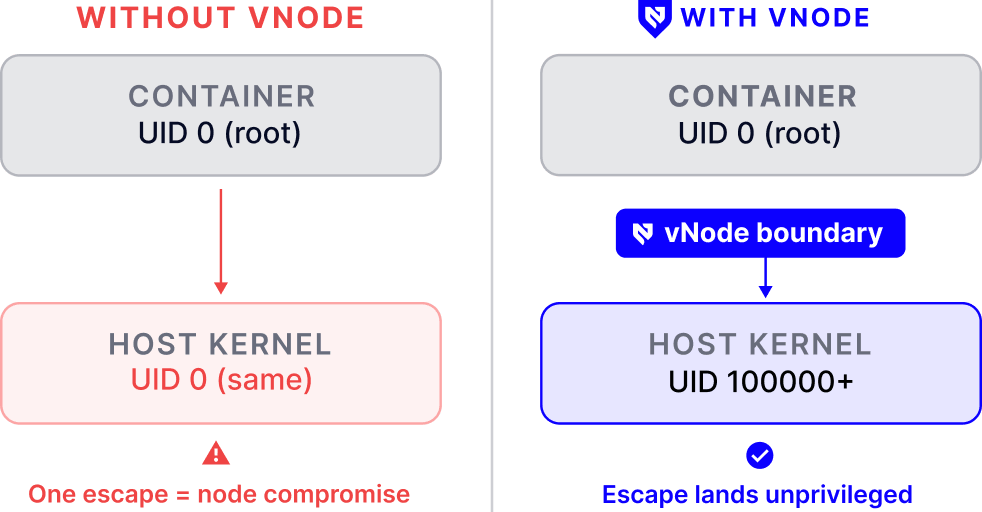
vNode uses Linux user namespaces and seccomp to restrict workload privileges and system calls. It adds runtime hardening for GPU service orchestration without a guest kernel or hypervisor, complementing dedicated workers rather than allocating GPUs.
This isn’t a side project. Behind every vCluster deployment is 5+ years of deep K8s engineering, security hardening, and battle-tested infrastructure work at massive scale.
Talk to our team about your stack
Deploy vCluster on your infra in minutes
Go live with a hyperscaler-grade tenant experience in days
vCluster is built for the whole GPU infrastructure stack. vMetal, the Infrastructure Orchestrator, provisions machines. vCluster Platform orchestrates tenant clusters, and vNode isolates workloads. The stack is designed for AI cloud providers running GPU workloads at scale, and it runs on 100K+ GPUs across 50+ GPU clouds & Fortune 500s.
Each tenant gets an isolated Kubernetes control plane running as a lightweight pod on the control plane cluster, with its own API server, data store, scheduler and RBAC. Tenants can't see each other's nodes, pods or platform internals. Private Nodes are the default, giving tenants dedicated worker nodes with per-tenant CNI and storage for hardware separation. Shared Nodes with resource quotas are available for your internal dev, test and CI.
Yes. vCluster Standalone runs as a binary directly on bare metal Linux with no dependency on k3s, kubeadm, or any external Kubernetes distribution. Combined with vMetal for zero-touch provisioning, the stack takes GPU servers from PXE boot through OS installation, network configuration, and into a production Kubernetes environment without any intermediate layers.
Boost Run went from decision to production launch in under 45 days for its managed Kubernetes service. That is a customer example rather than a promised implementation time. Your launch depends on machine inventory, driver configuration, networking, storage, templates and service integrations. vMetal and vCluster connect machine orchestration with tenant cluster delivery, reducing the infrastructure workflows you need to build yourself.
Yes. Every tenant cluster vCluster Platform provisions is a CNCF-certified Kubernetes control plane that serves standard Kubernetes APIs. Tenants get cluster-admin access to install their own CRDs, configure RBAC and run standard Kubernetes tooling, including GPU operators. vCluster is validated in NVIDIA's DGX reference architecture.
NVIDIA Run:AI is available through the native Certified Stacks integration, with release-specific prerequisites and templates. Its bundled templates do not automatically supply dedicated Private Nodes. Configure and validate the production worker model, GPU access, networking and storage before offering it to customers. Ray and Jupyter can use compatible Kubernetes deployment tooling and require their own supported configuration.
See how AI cloud providers go from GPU racks to managed Kubernetes on vCluster.
